


☕ Welcome to The Coder Cafe! How many times have you been torn between adding more tests and shipping? Today, we explore statistical vs. intellectual control applied to testing. Instead of chasing coverage numbers, we ask something more fundamental: whether we actually understand our code well enough to know what to test. I think this distinction is one of the most useful mental models for anyone writing tests. Get cozy, grab a coffee, and let’s begin!
Today’s Sponsor: CodeAF: nearly 4x Claude Code's solves, same model

On DeepSWE, CodeAF solved nearly 4× as many real GitHub issues as Claude Code on the same open model, at about half the cost per solve of the next-best harness. CodeAF is a new open-source coding harness built for open models like DeepSeek, Qwen, GLM and Kimi, and it works with any provider you choose. One small Go binary, Apache 2.0.
What Good Testing Actually Means
Let’s say we just finished coding a feature. Tests are green, coverage looks decent. We’re about to open a pull request. But a question crosses our mind: are the tests actually good enough?
Most developers reach for coverage at that point. If the number looks acceptable, they move on. But coverage is just a metric after all. It tells us which lines or branches ran during the tests, not whether our code is actually correct.
Indeed, even with high coverage, we may not understand our code well enough to know what could go wrong. In that case, we end up testing the wrong things, and the gaps stay invisible.
This is where George Fairbanks’ framework becomes useful. He draws a distinction between two modes of working with code: intellectual control and statistical control. Let’s explore what they mean and how they change the way we can think about testing.
Two Modes of Control
Fairbanks identifies two modes of working with code:
Intellectual control: We have a theory of how the code works in our head. We can reason about it, predict where it might break, and when we sit down to write tests, we’re not guessing at scenarios. Instead, we’re translating our understanding into assertions.
Statistical control: We don’t have that theory. We rely on the test suite to catch regressions. If the tests pass, we move forward. The tests act as guardrails.
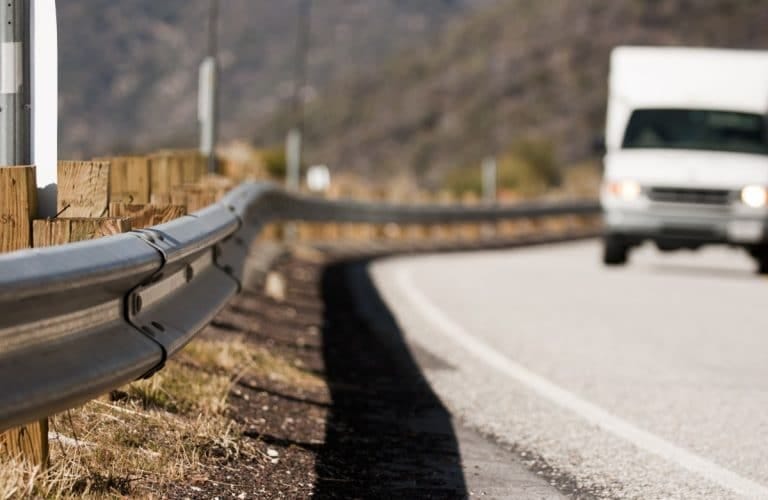
Fairbanks illustrates this with a metaphor. Imagine driving a car on a road with guardrails:
Intellectual control: We drive without hitting the rails. We know where the road goes.
Statistical control: We arrive at our destination after bouncing off the guardrails a few times. We got there, but we weren’t really in control.
Both modes are real. As developers, we rarely find ourselves fully in one or the other. We might have intellectual control over the module/component/package we just wrote and only statistical control over the legacy code we’re touching for the first time. And that’s fine. In a large codebase we didn’t write, statistical control is often the only honest starting position. The test suite is how we build understanding incrementally, until we can reason about the code rather than just lean on it. What matters is knowing which mode we're in, and whether we're moving in the right direction.
I experienced statistical control firsthand multiple times in my career. For example, working on a specific component at Google in the ML infrastructure space. The codebase was complex, the failure modes were non-obvious, and I hadn’t built it from scratch. When I needed to make changes, I didn’t have a full theory of how everything fit together. I relied heavily on a layer of functional tests to tell me whether my changes were breaking something. That’s statistical control: the tests were carrying understanding I didn’t have (yet).
Tests Check, They Don’t Test
This distinction gets sharper when we look at what automated tests actually do.
James Bach and Michael Bolton, two software testing practitioners, draw a line between checking and testing1:
Checking is what a machine does. It confirms that a specific assertion holds for a specific input. Given this input, do we get this output? That’s what our unit tests do. They check.
Testing is something different. Testing is an open-ended human investigation: exploring the system, asking what could go wrong, and discovering problems that no one anticipated. That activity happens in the developer’s head.
The implication is significant. Our test suite is only as good as the intellectual control behind it. A passing test suite doesn’t mean the code is correct. It means the scenarios we thought to check behaved as expected. If our understanding was incomplete, our checks were incomplete too.
This connects to what researchers call the oracle problem. An oracle, in testing, is what we use to decide whether an output is correct. For simple functions, the oracle is obvious: we know what the expected output should be. Think of a sorting function, given a list, we know exactly what the sorted result should look like:
Input:  [5, 1, 0, 9, 6]
Output: [0, 1, 5, 6, 9]
But for complex features, the oracle is not straightforward. Think of a fraud detection system:
Input:  Transaction (amount: $1,243, location: New-York, time: 2am)
Output: 0.4211214491
Is 0.4211214491 correct? Hard to say just by looking at the output. Someone has to understand the model, the business rules, and the risk thresholds well enough to know what score this transaction should produce, and therefore what the test should assert.
NOTE: In practice, many of us handle this by running the test, copying whatever value comes out, and pasting it as the expected value. We've probably all done it, and we've probably all felt how meaningless it was. This is statistical control: we're not asserting what the output should be, we're just recording what it happened to be. A better approach is to define meaningful bounds that reflect our actual understanding of the system, for instance asserting that this transaction scores above a
LIKELY_FRAUDthreshold but belowCERTAIN_FRAUD. Those thresholds don’t come from the code; they come from domain expertise, business rules, and knowledge of what the system is actually supposed to do. Defining them is itself an act of intellectual control, and they require their own validation. But someone has to do that thinking.
The test suite can verify an assertion, but it can’t invent one. That invention requires intellectual control. When we’re working under statistical control, that understanding is thin. We’re writing checks for the cases we’ve seen, not the cases we can reason about. Gaps in understanding become gaps in coverage, and those gaps are invisible.
Intellectual Control Belongs to the Team
Here’s where it gets practically important, and where I think Fairbanks’ framing could be extended.
When we write tests, we’re not writing them only for ourselves. We’re writing them for the next person who touches this code: a colleague picking up a bug fix, a new team member onboarding, or even ourselves in a few months (weeks?) after we’ve forgotten the details. Our mental model doesn’t transfer with the code. The tests are often the only artifact that can carry some of that understanding forward.
So intellectual control is a team property, and that changes what “good enough” means.
Imagine a module that we understand deeply. We wrote it, we know its invariants, we can reason about its edge cases. For us, right now, unit tests might be enough. We have the theory in our head, and the tests express it faithfully.
Now imagine someone new joins the team. They read the code. They don’t have our background. They can’t tell which edge cases matter, which inputs are dangerous, which failure modes are emergent rather than obvious. For them, the same unit test suite might be far from enough. Without the shared understanding, the tests are a partial map of a territory they don’t know how to read.
So the right question isn’t just “Do we understand this code?” It’s “Could someone new to this code understand it well enough to reason about what to test?”
A Practical Heuristic
So how do we know our code is properly tested? A test is only as good as the understanding behind it. A useful heuristic: for each test we wrote, can we articulate what we’re protecting against and why it matters?
If we can, we have intellectual control.
If we can’t, that’s a signal. Not necessarily that we need more tests, but that we may not understand the code well enough to know what to test in the first place.
For example, if we wrote a test for our fraud detection model, we should be able to say: “This test protects against the model assigning a low risk score to transactions that happen in a new location right after a large purchase.” If all we can say is “This test covers the location field,” we’re checking, not testing.
And that understanding also determines what kind of tests we need:
When we have intellectual control over it, unit tests are often enough. They flow naturally from our understanding and capture what matters.
When we don’t, we need something heavier, such as integration tests or end-to-end tests. They become the primary way to build and share the understanding we’re missing.
That’s intellectual control in practice: knowing what we’re protecting, and why.
AI to the Rescue?
There’s a tempting shortcut that’s become increasingly common: delegate test writing to AI. Let the model generate the test suite, watch coverage climb, and move on.
The problem is that AI has no external ground truth. It cannot access the business rules, the production incident history, or the user behavior context that define what correct actually means. It can only check what it can infer from the code itself. But the code is precisely what we're trying to validate. AI-generated tests are statistical control by definition: they sample the output space based on what's visible in the code, not based on a theory of what could go wrong. Delegating tests to AI automates the checking, which was already the weaker half.
There’s also a subtler risk. AI-generated tests can create a false sense of intellectual control. Coverage goes up, tests multiply. Everything looks thorough. But the understanding behind those tests is thin or borrowed from the code itself. The tests end up reflecting the implementation back at us rather than independently verifying behavior. We’re not testing the code against our understanding of the problem. We’re testing the code against itself.
The oracle problem doesn’t go away either. Someone still has to decide what correct looks like, and that can’t be the AI. It simply doesn’t have the context. And yet, this is where some are heading (this is an excerpt of a LinkedIn post titled Unit Tests Are Dead: Long Live AI-Inferred Code Coverage):

Replacing “What’s our test coverage?” with “How confident is our AI?” doesn’t solve the oracle problem. It just moves it one level up. The AI infers behavior from the code, but the code is precisely what we’re trying to validate. There’s no external ground truth. Only someone who understands the system, the business rules, and the expected behavior can decide what correct looks like.
That said, AI is genuinely useful for the mechanical part: generating boilerplate checks for obvious cases, catching regressions on well-understood code. That’s fine. But it can’t (for now) substitute for the human work of building a theory of the system.
Summary
Coverage tells us which lines ran, not whether we understood our code well enough to test the right things.
Intellectual control means having a theory of how the code works. Statistical control means relying on the test suite to catch what we didn’t think of.
A passing test suite doesn’t mean the code is correct. It means the scenarios we thought to check behaved as expected.
Intellectual control is a team property, not a personal one. Tests are often the only artifact that carries understanding forward.
A useful heuristic: for each test we wrote, can we articulate what we’re protecting against and why it matters?
AI-generated tests are statistical control by definition. They reflect the code back at itself, not our understanding of the problem.
Resources
More From the Testing Category
Sources
Simple Made Easy:
This distinction is debated in the testing community, but still helpful in the context of this post, in my opinion.